NSRL MODEL EVALS

NSRL-MME v0 Is Measured And Failing

The current headline floor is 37.1% against the 70.0% target; the gates below show what must be fixed next.

Generated
2026-08-30T08:57:50.126Z
Commit
c63e3ca96e41
Workflow
run 33

HEADLINE

NSRL-MME v0 Multimodal LLM Eval

failed
Headline score
37.1%
Floor across model-native multimodal task families.
Target
70.0%
All required gates must also be green.
MME artifact
present
data/processed/nsrl-mme-v0.json
Quality report
present
data/processed/nsrl-mme-v0-local-smoke-20260709T0752Z/quality-report-clean-72-eval500-v2.json
Objective coverage
present
data/processed/objective-coverage.json

Sampler, replay, browser-probe, and memory-assisted sample metrics are diagnostics only; they do not define the headline score.
text prompt -> symbolic image plan
43.9%

432 rows / confidence_trace.directional_native_eval.groups.text_prompt_to_image_plan.stats

seal image -> identity / attributes / source text
43.4%

720 rows / confidence_trace.directional_native_eval.groups.seal_image_to_text.stats

text + seal -> grounded explanation / match
37.1%

576 rows / confidence_trace.directional_native_eval.groups.text_and_seal_to_explanation.stats

prompt/name -> identity / source binding
37.5%

720 rows / confidence_trace.directional_native_eval.groups.identity_source_binding.stats

match / no-match hard-negative agreement
100.0%

313 rows / confidence_trace.cross_modal_agreement

green quality report with confidence trace
not green

Required gate for passing NSRL-MME v0.

local objective coverage proof
green

Required gate for passing NSRL-MME v0.

source-grounded text/image evidence
green

Required gate for passing NSRL-MME v0.

held-out generated output integrity
not green

Required gate for passing NSRL-MME v0.

SCOREBOARD

Models On Our Evals

4 model paths

NSRLLMM1

attention joint text/image-token model

probe-gated + raw control

Current browser artifact path. The probe suite exercises prompt-scoped text, embedded image memory, raw name logits, and source-specific body-start logits. The raw no-memory row is a free-running negative control and should not be read as browser-path quality.

Artifact probe suite
72/72
100%. All configured prompt samples passed the browser sampler gate.
Constrained name-logit top-1
72/72
100%. Expected spirit name token after `Solomon selects `; median rank 1; worst rank 1.
Constrained body-start top-1
72/72
100%. First source prose token after the name opening; median rank 1; worst rank 1.
Raw no-memory name match
0.0%
0 per mille from raw-no-memory / 72 prompts / 0xff009204cd3d1767 (prompt_name_match_per_mille).
Raw text quality score
27/100
mean_raw_quality_score from raw-no-memory / 72 prompts / 0xff009204cd3d1767.
Raw scaffold outputs
76.3%
763 per mille from raw-no-memory / 72 prompts / 0xff009204cd3d1767 (scaffold_output_per_mille).
  • scripts/check-solomon-attention-web-quality.mjs --all-names --summary
  • scripts/probe-solomon-attention-raw-rank.mjs --all-names --summary
  • scripts/probe-solomon-attention-body-start-rank.mjs --summary
  • docs/solomon-attention-eval.tsv

NSRLLAT1

prompt-to-layout latent prior

published evals

Prompt/layout prior measured on checked-in train/eval/gold prompt partitions and the clean 72 held-out generation prompt set. The clean-72 row is the fast planner target to improve before rerunning bitmap generation.

Clean-72 planner top-1
4.1%
41 per mille from ld128tf1024 / 72 prompts (top1_per_mille).
Clean-72 planner top-5
8.3%
83 per mille from ld128tf1024 / 72 prompts (top5_per_mille).
Best eval top-1
20.0%
200 per mille from 576 prompt rows / latent 32 / text 512 / 0ce31085 (eval_top1_per_mille).
Best eval top-5
46.2%
462 per mille from 576 prompt rows / latent 32 / text 512 / 0ce31085 (eval_top5_per_mille).
Best gold top-1
25.0%
250 per mille from 288 prompt rows / latent 32 / text 512 / c98fc237 (gold_top1_per_mille).
Best shape-probe eval top-1
23.7%
237 per mille from 576 prompt rows / latent 128 / text 8192 / 4fcc02bd (eval_top1_per_mille).
  • docs/solomon-latent-planner-eval.tsv
  • docs/solomon-eval-scaling-curve.tsv
  • docs/solomon-text-feature-shape-probe.tsv

NSRLTCH

text-conditioned bitmap denoiser

published evals

The denoiser artifact is scored on learned latent-conditioned generations. The oracle-conditioning diagnostic is an upper bound only: it gives the denoiser the true 16x16 target plan to separate planner failure from renderer/retrieval failure.

Published artifact
present
10.3 KiB / sha256 a60497cd3720
Best generated top-1
4.1%
41 per mille from centroid16 / 24 prompts (top1_per_mille).
Best generated top-5
4.1%
41 per mille from centroid16 / 24 prompts (top5_per_mille).
Best latent top-1
8.3%
83 per mille from centroid16 / 24 prompts (latent_top1_per_mille).
Oracle-plan signature top-1
98.6%
986 per mille from 72 prompts (signature_top1_per_mille).
Oracle-plan retrieval top-1
18.0%
180 per mille from 72 prompts (retrieval_top1_per_mille).
Best target distance
5,849,621
mean_generated_target_distance_q8 from aws-e8 / 24 prompts. Lower is better.
  • web/assets/solomon-model.nsrltch
  • docs/solomon-generative-eval.tsv
  • docs/solomon-oracle-condition-diagnostic.tsv

NSRLMOD1

coarse joint text/image-token model

published evals

The multimodal fallback artifact is scored on tracked corpus replay: next-token ranks over prompt bytes, generated text bytes, marker tokens, and 16x16 image bins. This is artifact-native replay quality, not broad free-running quality.

Published artifact
present
17.1 MiB / sha256 ef57fc5ad94c
Overall replay top-1
99.4%
994 per mille from deployed / 313 examples / 0x8057e681de909abc (overall_top1_per_mille).
Text replay top-1
99.6%
996 per mille from deployed / 313 examples / 0x8057e681de909abc (text_top1_per_mille).
Image-token top-1
100.0%
1000 per mille from deployed / 313 examples / 0x8057e681de909abc (image_top1_per_mille).
Exact examples
0.3%
3 per mille from deployed / 313 examples / 0x8057e681de909abc (exact_examples_per_mille).
  • web/assets/solomon-multimodal.nsrlmod
  • docs/solomon-multimodal-eval.tsv
  • scripts/run-solomon-multimodal-eval.mjs

SAMPLES

Representative Eval Panels

5 panels

NSRLLAT1

Latent Prior Routing

Best checked-in routing row

Prompt-to-layout routing is scored on held-out Solomon prompt partitions. This panel shows the strongest eval top-1 row now published.

Eval top-1
20.0%
Eval top-5
46.2%
Gold top-5
27.7%
  • docs/solomon-eval-scaling-curve.tsv
  • 576 prompt rows / latent 32 / text 512 / 0ce31085

NSRLTCH

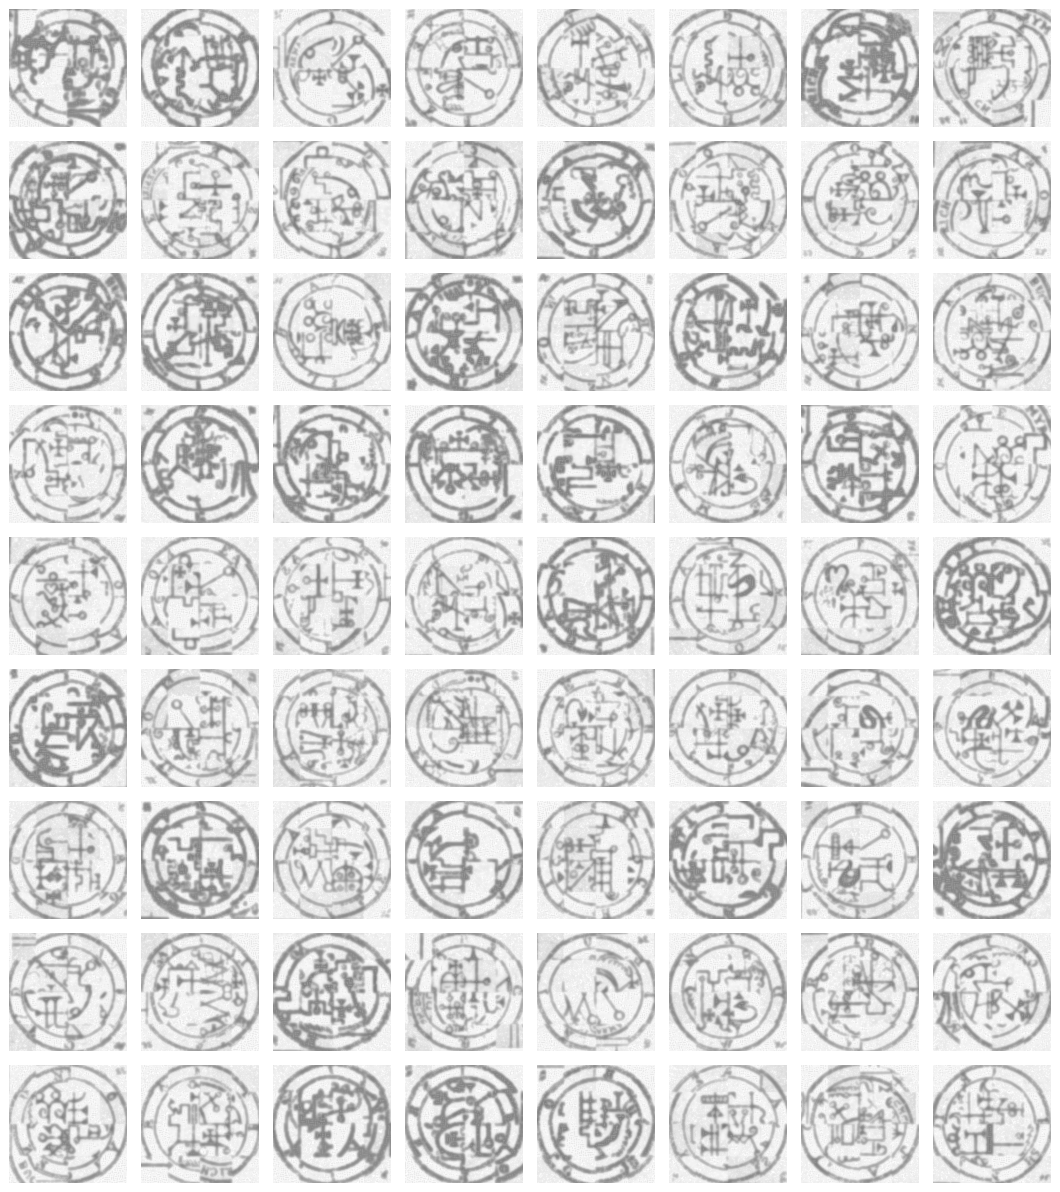
Generated Seal Retrieval

Class-head generation eval
NSRLTCH text-conditioned seal panel

Generated bitmap seals are checked against target retrieval. The image panel is the tracked visual sample; the numbers come from the generative eval table.

Generated top-1
4.1%
Generated top-5
4.1%
Latent top-1
8.3%
  • docs/solomon-generative-eval.tsv
  • docs/assets/solomon-text-conditioned-seals.png

NSRLTCH

Oracle Conditioning Split

Diagnostic upper bound; not headline evidence

The denoiser receives the true held-out 16x16 target plan here. This isolates the current failure: the learned planner is the first blocker, while rendered-image retrieval remains a separate weak gate.

Signature top-1
98.6%
Signature top-5
100.0%
Retrieval top-1
18.0%
Retrieval top-5
52.7%
  • docs/solomon-oracle-condition-diagnostic.tsv
  • scripts/run-solomon-oracle-condition-diagnostic.mjs

NSRLMOD1

Text/Image Token Replay

Tracked corpus replay

The multimodal artifact is scored on next-token replay over prompt bytes, generated text bytes, marker tokens, and 16x16 image bins.

Overall top-1
99.4%
Text top-1
99.6%
Image top-1
100.0%
Context hit
100.0%
  • docs/solomon-multimodal-eval.tsv
  • deployed / 313 examples / 0x8057e681de909abc

NSRLLMM1

Probe-Gated Artifact, Raw Control

Browser probes pass; raw no-memory control fails name binding

The browser artifact path is probe-gated separately from native free-running sampling with memory and conditioning disabled.

seal of Bael
---He is of the Goetia and teacheth with his ART in LINE.
Artifact prompts
72/72
Name-logit top-1
72/72
Body-start top-1
72/72
Raw name match
0.0%
Raw text score
27/100
  • docs/solomon-attention-eval.tsv
  • scripts/check-solomon-attention-web-quality.mjs --all-names --summary

EVIDENCE

Published Eval Inputs

31 table rows
Headline NSRL-MME v0
37.1%

Status: failed. Floor score across model-native multimodal task families.

Honesty guard
passed

CI fails when claimed model coverage lacks checked-in rows, probes, assets, or samples.

Prompt sample gallery
6 rows

Fixed NSRLLMM1 prompt samples with copied PNGs and a TSV trace.

Attention artifact probes
3/3 passed

Prompt/text/image checks run against the browser artifact.

Attention raw eval table
1 rows

NSRLLMM1 no-memory native sampling control row.

Latent prior tables
19 rows

Prompt routing, shape, and text-feature sweeps.

Generative eval table
2 rows

Held-out generated bitmap eval rows, when checked in.

Multimodal eval table
1 rows

NSRLMOD1 prompt/text/image-token replay rows.

ATTENTION ARTIFACT

Probe Details

3/3 passed

passed

Browser artifact quality

Prompts
72
All Names
true

passed

Raw prompt-name rank

Prompts
72
Ranked
72
Top 1
72
Top 5
72
Top 10
72
Median Rank
1
Worst Rank
1
Median Margin Q8
4064
Worst Margin Q8
4064

passed

Body-start rank

Prompts
72
Ranked
72
Top 1
72
Top 5
72
Top 10
72
Median Rank
1
Worst Rank
1
Median Margin Q8
1391
Worst Margin Q8
1

ARTIFACTS

Published Files

ArtifactStatusBytesSHA-256
NSRLLMM1 attention artifact present 62.1 KiB 60826f8b823f3bc6
NSRLMOD1 multimodal artifact present 17.1 MiB ef57fc5ad94cda62
NSRLTCH denoiser artifact present 10.3 KiB a60497cd37201ede
Solomon text signature index present 104.8 KiB 34c0227d0f54ab5c

Prior Scaling Curve

12 rows
eval_top1_per_mille
200
576 prompt rows / latent 32 / text 512 / 0ce31085
eval_top5_per_mille
462
576 prompt rows / latent 32 / text 512 / 0ce31085
gold_top1_per_mille
250
288 prompt rows / latent 32 / text 512 / c98fc237
prompt_rowsn_train_promptslatent_dimtext_featureseval_top1_per_milleeval_top5_per_millegold_top1_per_millegold_top5_per_millemodel_hash
2881153251234275250506c98fc237
288115645120241104326ca117469
2881151285123424197326f67981cf
57635232512200462762770ce31085
5763526451213736297229be26f0d7
5763521285121873628322257d13997
115282232512862316222265047fbd
1152822645126421576256a2a510ad
115282212851275231104256e8f9bf91
14251040325126624041222d3ea03af
14251040645124924462243134230e1
1425104012851249219972844e63b0ad

Text Feature Shape Probe

6 rows
eval_top1_per_mille
237
576 prompt rows / latent 128 / text 8192 / 4fcc02bd
novel_top1_per_mille
291
576 prompt rows / latent 128 / text 8192 / 4fcc02bd
gold_top5_per_mille
416
576 prompt rows / latent 32 / text 2048 / 04993d13
prompt_rowslatent_dimtext_featureseval_top1_per_milleeval_top5_per_millenovel_top1_per_millegold_top1_per_millegold_top5_per_millemodel_hash
57632204822553720816641604993d13
576328192212537208173388b801e8fd
576642048187487125159333127e2a41
5766481921754371661523195e6dfa75
5761282048137437166145326d1b4e7ed
57612881922374622911382774fcc02bd

Text Feature Probe

1 rows
eval_top1_per_mille
212
576 prompt rows / latent 32 / text 8192 / b801e8fd
novel_top1_per_mille
208
576 prompt rows / latent 32 / text 8192 / b801e8fd
gold_top5_per_mille
388
576 prompt rows / latent 32 / text 8192 / b801e8fd
prompt_rowslatent_dimtext_featureseval_top1_per_milleeval_top5_per_millenovel_top1_per_millegold_top1_per_millegold_top5_per_millemodel_hash
576328192212537208173388b801e8fd

Generative Eval

2 rows
top1_per_mille
41
centroid16 / 24 prompts
top5_per_mille
41
centroid16 / 24 prompts
latent_top1_per_mille
83
centroid16 / 24 prompts
modelpromptstop1_per_milletop5_per_millelatent_top1_per_millelatent_top5_per_millemean_generated_target_distance_q8text_weight
centroid1624414183125606278496
aws-e82441414141584962196

Latent Planner Eval

1 rows
top1_per_mille
41
ld128tf1024 / 72 prompts
top5_per_mille
83
ld128tf1024 / 72 prompts
run_idmodelpromptstop1_per_milletop5_per_millemean_rank_q8mean_target_distance_q8latent_model_hashconclusion
clean72-ld128tf1024ld128tf1024724183925542658520xa620d349f9f336adlearned decoded latent plans only identify 3 of 72 held-out prompts at top-1, confirming the prompt-to-signature planner is the first blocker before bitmap rendering

Oracle Conditioning Diagnostic

1 rows
signature_top1_per_mille
986
72 prompts
retrieval_top1_per_mille
180
72 prompts
retrieval_top5_per_mille
527
72 prompts
run_iddiagnostic_onlypromptssignature_top1_per_millesignature_top5_per_milleretrieval_top1_per_milleretrieval_top5_per_millemean_signature_rank_q8mean_retrieval_rank_q8conclusion
v1-oracle-l72-c1-p1true7298610001805272592549true 16x16 conditioning nearly solves signature identity, so the learned prompt-to-signature planner is the first blocker; rendered retrieval identity remains weak and separate

Multimodal Eval

1 rows
overall_top1_per_mille
994
deployed / 313 examples / 0x8057e681de909abc
text_top1_per_mille
996
deployed / 313 examples / 0x8057e681de909abc
image_top1_per_mille
1000
deployed / 313 examples / 0x8057e681de909abc
modeleval_scopeexamplesoverall_top1_per_milletext_top1_per_milleimage_top1_per_milleprompt_top1_per_milleexact_examples_per_millecontext_hit_per_millemodel_hash
deployedtracked_corpus_replay3139949961000882310000x8057e681de909abc

Attention Raw Eval

1 rows
prompt_name_match_per_mille
0
raw-no-memory / 72 prompts / 0xff009204cd3d1767
mean_raw_quality_score
27
raw-no-memory / 72 prompts / 0xff009204cd3d1767
distinct_texts
4
raw-no-memory / 72 prompts / 0xff009204cd3d1767
modeleval_scopepromptsprompt_name_match_per_millemean_raw_quality_scoremin_raw_quality_scoredistinct_textsscaffold_output_per_millemodel_hash
raw-no-memorynative_raw_no_memory_no_conditioning720271547630xff009204cd3d1767
6 rows
modelprompt_idprompt_kindprompttext_sourceimage_sourcetext_lm_fallbacktextimage_pathmodel_hash
NSRLLMM1baelfixed-knownseal of Baelembedded_text_lm_strictembedded_image_memory_strictfalseSolomon selects Bael: He maketh thee to go Invisible.docs/assets/results-samples/bael.png0xff009204cd3d1767
NSRLLMM1stolasfixed-knownseal of Stolasembedded_text_lm_strictembedded_image_memory_strictfalseSolomon selects Stolas: He teacheth the Art of Astronomy, and the Virtues of Herbs and Precious Stones.docs/assets/results-samples/stolas.png0xff009204cd3d1767
NSRLLMM1marbasfixed-knownseal of Marbasembedded_text_memory_guardembedded_image_memory_stricttrueSolomon selects Marbas: He is a Great President, and appeareth at first in the form of a Great Lion, but afterwards, at the request of the Master, he putteth on Human Shape.docs/assets/results-samples/marbas.png0xff009204cd3d1767
NSRLLMM1genericfixed-genericking solomon sealembedded_text_lm_strictembedded_image_memory_strictfalseSolomon selects Ronove: He teacheth the Art of Rhetoric very well and giveth Good Servants, Knowledge of Tongues, and Favours with Friends or Foes.docs/assets/results-samples/generic.png0xff009204cd3d1767
NSRLLMM1eastern-kingfixed-held-out-phraseeastern king invisible spiritembedded_text_memory_guardembedded_image_memory_stricttrueSolomon selects Marbas: He is a Great President, and appeareth at first in the form of a Great Lion, but afterwards, at the request of the Master, he putteth on Human Shape.docs/assets/results-samples/eastern-king.png0xff009204cd3d1767
NSRLLMM1owl-astronomyfixed-held-out-phraseowl astronomy sealembedded_text_lm_strictembedded_image_memory_strictfalseSolomon selects Murmur: and appeareth in the Form of a Warrior riding upon a Gryphon, with a Ducal Crown upon his Head.docs/assets/results-samples/owl-astronomy.png0xff009204cd3d1767